A short Python demonstration is putting fresh attention on Jev, a new AI model from TypeSafe designed to make fast, structured decisions rather than generate conversational text.
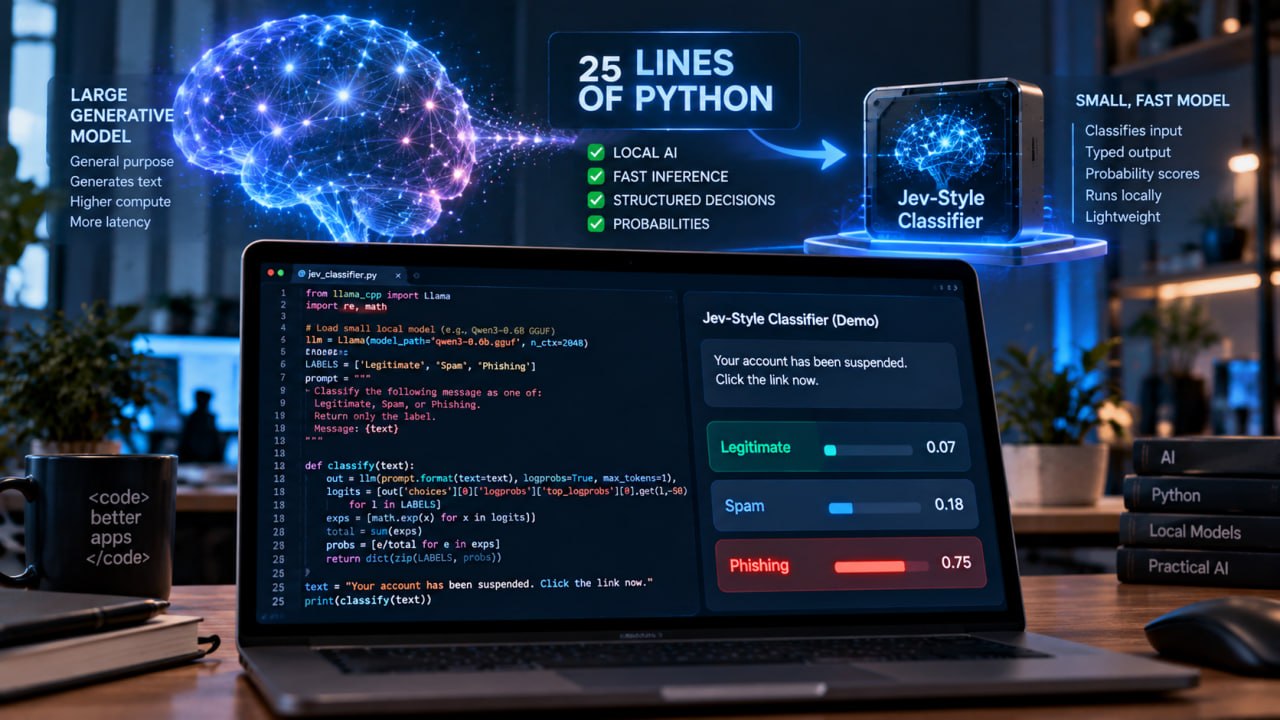
The demonstration, published by Duarte O. Carmo of NobodyWho, shows how a similar decision-making workflow can be built in roughly 25 lines of Python using an open-source Qwen3 0.6B model and llama.cpp. The author explicitly describes the post as a parody rather than a complete implementation of the commercial Jev system.
That distinction matters. The code does not reproduce Jev's proprietary model, training process or reported performance. Instead, it demonstrates a simpler underlying idea: a language model can be prompted to choose between predefined options, and its token probabilities can be extracted to produce a lightweight classification system.
The result has sparked discussion about what makes Jev technically interesting—and which parts of the system are actually difficult to reproduce.
What Is Jev?
Jev is TypeSafe AI's first System One Model, announced in September 2026.
Unlike conventional large language models, Jev is designed not to write paragraphs of text. TypeSafe describes it as a model that takes context and focused questions and returns structured decisions that software can use directly.
For example, a conventional AI assistant might read a customer-support message and respond:
> "This appears to be a billing issue and should probably be routed to the payments team."
Jev's intended approach is much more structured. A developer could define categories such as:
- Billing
- Technical support
- Account access
- Other
The model can then return a typed decision and probabilities that software can act on.
TypeSafe says Jev is designed for tasks such as classification, routing, filtering, scoring and deciding which action an AI agent should take.
Why Is Jev Different From a Normal LLM?
Most generative AI models are optimized to produce text.
That is extremely useful when the task involves writing an email, explaining a concept, generating code or summarizing a document. But software often needs much simpler decisions.
A backend application may only need to know:
- Should this ticket go to billing?
- Should this request be escalated?
- Which tool should an AI agent use?
- Is this message suspicious?
- Does this document need human review?
Generating a paragraph to answer those questions can be inefficient.
TypeSafe's argument is that software should receive a structured decision directly instead of forcing a general-purpose language model to generate text that another program then has to interpret.
That is the basic idea behind the System One concept.
What the 25-Line Python Demo Actually Does
The NobodyWho demonstration takes a much simpler route.
It loads a small Qwen3 0.6B model in GGUF format through llama.cpp, creates a prompt containing several possible choices, and examines the model's logits for the corresponding answer tokens.
The example uses three categories:
- Legitimate
- Spam
- Phishing
The input is an example email asking a payroll recipient to provide credentials through a non-company sign-in page.
Instead of asking the model to write an explanation, the code looks at the scores associated with the possible choices.
Those scores are then converted into probabilities.
The demonstration produces approximately:* Legitimate: 3.1%
- Spam: 8.4%
- Phishing: 88.5%
The phishing category therefore receives the highest probability in the example.
The Key Trick: Read the Model's Logits
The interesting technical detail is how little code is required.
A language model normally predicts what token should come next. If the developer has constrained the possible answers to a small set of tokens, those next-token scores can be compared.
Suppose the model has to choose between:
- A = Legitimate
- B = Spam
- C = Phishing
The program can inspect the model's score for A, B and C.
Those raw scores, called logits, can then be normalized into probabilities.
Conceptually, the process is:
- Provide the model with the input.
- Define the permitted choices.
- Run the model.
- Read the logits for the relevant choice tokens.
- Normalize the values.
- Return the resulting probabilities.
That is the core technique demonstrated by the 25-line implementation.
But the 25-Line Demo Is Not Actually Jev
This is the most important clarification surrounding the story.
The NobodyWho post intentionally makes a provocative comparison with Jev. Its author explicitly says the demonstration does not use Jev's API, synthetic training data or TypeSafe's Reinforcement Learning for Calibrated Decisions (RLCD).
TypeSafe says Jev is built as a different class of model and uses a training approach called RLCD, which stands for Reinforcement Learning for Calibrated Decisions. The company says RLCD is intended to train the model to produce decisions with probabilities that correspond more closely to real-world outcomes.
The internal architecture and training details of Jev are not fully public.
That means the 25-line program should be understood as a Jev-style demonstration, not a replacement for Jev.
Why the Demonstration Still Matters
The parody works because it highlights a genuine engineering question.
If a software application only needs a classification decision, does it need a large frontier model generating text?
In some situations, probably not.
A smaller local model can potentially handle narrow classification tasks much more efficiently, particularly when the choices are clearly defined.
That could make this approach useful for high-volume operations such as:
- Email classification
- Support-ticket routing
- Content filtering
- Document triage
- Fraud screening
- AI-agent tool selection
- Human-review routing
- Basic relevance scoring
The important word is potentially. Real production systems still need to measure accuracy, calibration, latency and failure rates on their own data.
Jev's Actual Advantage Is Not Just Classification
Jev's public positioning goes beyond the ability to classify text.
TypeSafe says Jev is designed to return structured decisions with calibrated probabilities and confidence information. Its model is intended to be integrated directly into software rather than used primarily as a conversational interface.
TypeSafe also says Jev can operate at substantially lower cost and latency than frontier generative models. The company's current public materials advertise a price of about $0.042 per million input tokens, with output free, while describing Jev as designed for very fast decision workloads.
Those are vendor claims, however, and performance can vary significantly depending on the workload.
The key differentiator TypeSafe is selling is therefore not simply "AI classification." It is the combination of:
- Structured outputs
- Fast inference
- Low operating cost
- Probability estimates
- Automation-focused design
- A training objective centered on calibrated decisions
What Does RLCD Mean?
RLCD stands for Reinforcement Learning for Calibrated Decisions.
TypeSafe presents it as an alternative to training approaches commonly associated with general-purpose language models.Traditional reinforcement learning approaches can optimize models toward human preferences or verifiable answers. TypeSafe says RLCD instead focuses on making the model's probabilities correspond to actual outcomes over many decisions.
For example, if a system repeatedly assigns an 80% probability to an outcome, a well-calibrated system should see that outcome occur roughly 80% of the time across a sufficiently large set of comparable predictions.
That does not mean an individual prediction with 80% confidence has an 80% guarantee of being correct.
Calibration is a property measured across groups of predictions, not a promise about any single decision.
Where the 25-Line Approach Has Limitations
The simple Python demonstration is clever, but there are technical limitations.
Token probabilities are not automatically calibrated
A model's next-token probabilities are not necessarily trustworthy probabilities for real-world events.
The model may strongly prefer one token because of how it was trained to generate text, even if that token does not correspond to an accurately calibrated real-world probability.
This is one reason TypeSafe emphasizes calibration as part of Jev's design.
Choice labels can affect results
The demonstration relies on tokens such as A, B and C.
The probability associated with one token can depend on tokenization, prompt wording and the model's learned preferences.
Discussions around the Hacker News post raised concerns about probability mass being affected by the model's tendency to continue generating prose rather than making a clean categorical decision.
A small model can still make mistakes
Using a 0.6-billion-parameter model locally has major advantages for speed and cost, but smaller models can have less knowledge and reasoning capability than frontier systems.
The right question is therefore not whether a tiny model can imitate the interface.
It is whether it performs well enough on the specific decision task being automated.
Local AI Is Another Important Part of the Story
The 25-line implementation also demonstrates something attractive for privacy-conscious developers: the model can run locally.
The NobodyWho example uses a local GGUF model through llama.cpp, meaning the classification request does not need to be sent to a cloud API.
That can matter for applications involving sensitive information.
A company could potentially classify documents, emails or internal records without sending the underlying content to an external inference provider.
Of course, local inference brings its own requirements, including model downloads, hardware resources, updates and performance optimization.
Could This Replace Large AI Models?
Not broadly.
A decision model and a generative model serve different purposes.
A system like Jev is designed for bounded decisions. A general-purpose LLM can write text, reason through open-ended problems, generate code and handle tasks where the correct output is not known in advance.
A practical AI application could therefore use both.
For example:
- A large model receives a complex user request.
- A smaller decision model determines which workflow should handle it.
- Traditional software executes deterministic operations.
- A human is asked to review uncertain cases.
- The large model is called again only when deeper reasoning or generation is required.
This kind of architecture could reduce the number of expensive frontier-model calls without removing them entirely.
The Bigger Lesson From "Jev in 25 Lines"
The viral reaction to the post says something interesting about the current AI market.
AI developers are increasingly looking beyond giant language models for every problem.
Sometimes the best architecture may involve several specialized components rather than one enormous model doing everything.A large model can handle open-ended reasoning and generation. A smaller model can handle classification. Traditional code can handle exact calculations and permissions. Search systems can retrieve information. Humans can handle high-risk decisions.
The 25-line Jev demonstration makes that architectural idea unusually easy to see.
But it should not be mistaken for proof that Jev itself is trivial to reproduce.
The hardest part of a production decision model may not be writing the inference code. It may be obtaining reliable training data, achieving genuine probability calibration, evaluating edge cases and proving that the model remains dependable when deployed at scale.
What Happens Next for Jev?
Jev is part of a broader movement toward machine-native AI interfaces.
Instead of asking AI systems to produce text for another program to parse, developers can increasingly design models that return information directly in the form software needs.
TypeSafe describes this as moving from "strings" toward structured decisions.
Whether that becomes a major model category will depend on real-world adoption and independent evaluation.
The current discussion is therefore less about whether 25 lines of Python can literally recreate Jev and more about whether specialized decision models can become an important layer between large AI systems and traditional software.
Final Takeaway
The viral "Jev in 25 Lines of Python" demonstration is not a full open-source recreation of TypeSafe's Jev model.
It is a deliberately simple example showing that a small local language model can be turned into a structured classifier by examining logits for predefined choices. The example uses Qwen3 0.6B with llama.cpp and produces probability scores for categories such as legitimate, spam and phishing.
Jev itself is more ambitious. TypeSafe describes it as a System One decision model trained with RLCD and designed to provide fast, structured and calibrated decisions for software and AI-agent workflows.
The real takeaway is not that Jev has been reduced to 25 lines of Python. It is that the AI stack may be moving toward a more specialized architecture where generative models handle complex reasoning while smaller decision systems handle the countless simple judgments happening around them.
That could make AI applications faster, cheaper and easier to automate—but proving that these systems make reliable decisions will remain the harder engineering challenge.
Frequently Asked Questions
What is Jev in AI?
Jev is TypeSafe AI's first System One model, designed to return structured decisions and probabilities rather than generate conversational text.
What does "Jev in 25 Lines of Python" mean?
It refers to a NobodyWho demonstration that recreates a simplified Jev-style classification workflow using approximately 25 lines of Python, Qwen3 0.6B and llama.cpp. It is a parody demonstration, not the actual Jev model.
Can I run the 25-line Jev-style example locally?
The demonstration is designed around a local GGUF model running through llama.cpp, so the basic approach can run locally on suitable hardware.
Is the 25-line Python implementation the real Jev model?
No. TypeSafe says Jev uses its own System One architecture and RLCD training approach. The 25-line example does not reproduce those proprietary components.
What is RLCD in Jev?
RLCD means Reinforcement Learning for Calibrated Decisions. TypeSafe says it is a training approach designed to make decision probabilities correspond more closely to real-world outcomes.